

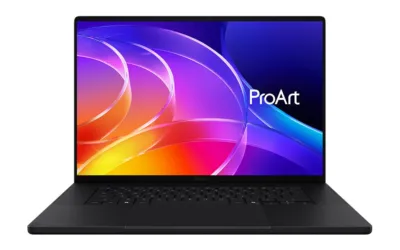
Hardware · NVIDIA
What AI models can the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB) run?
- Unified memory
- 32.0 GB
- Usable for models
- 16.0 GB
- Memory bandwidth
- 300 GB/s
- FP16 compute
- 24.0 TFLOPS
- Released
- 2026
macOS lets the GPU use roughly two-thirds to three-quarters of unified memory by default, so we plan around that figure rather than the full 32.0 GB.
More about this hardware
| Maker | NVIDIA |
|---|---|
| Type | Unified-memory system on a chip |
| GPU share of memory | 50% (what the GPU can typically be given for a model) |
| Chip | NVIDIA RTX Spark N1X (5120-core GPU) |
Apps that run models well on the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
5 products with the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
Best LLMs for the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 77Great quality (A) · 77 of 100: how capable the model is at Q3_K_M, whatever it runs on. Match score 88/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 26B-A4B | Q3_K_M | 14.9 GB | 89.1 tok/s | Runs welltight fit |
| 78Great quality (A) · 78 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 87/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 12B | Q4_K_M | 9.8 GB | 30.8 tok/s | Runs great |
| 76Great quality (A) · 76 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 86/100 (quality, fit, speed and memory use) sets the ranking. | K2 Horizon 7B | Q4_K_M | 8.6 GB | 40.9 tok/s | Runs great |
| 70Great quality (A) · 70 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 86/100 (quality, fit, speed and memory use) sets the ranking. | Nemotron 3.5 Bolt E4B | Q8_0 | 10.5 GB | 41.7 tok/s | Runs great |
| 69Good quality (B) · 69 of 100: how capable the model is at Q6_K, whatever it runs on. Match score 86/100 (quality, fit, speed and memory use) sets the ranking. | Mellum2.1 Thinking (12B-A2.5B) | Q6_K | 12.0 GB | 74.7 tok/s | Runs great |
| 68Good quality (B) · 68 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 85/100 (quality, fit, speed and memory use) sets the ranking. | Gemma 4 E4B | Q8_0 | 10.5 GB | 41.7 tok/s | Runs great |
| 70Great quality (A) · 70 of 100: how capable the model is at MXFP4, whatever it runs on. Match score 85/100 (quality, fit, speed and memory use) sets the ranking. | gpt-oss 20B | MXFP4 | 14.0 GB | 80.0 tok/s | Runs welltight fit |
| 74Great quality (A) · 74 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 84/100 (quality, fit, speed and memory use) sets the ranking. | SenseNova Loop 9B Preview | Q4_K_M | 8.2 GB | 38.1 tok/s | Runs great |
| 74Great quality (A) · 74 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 84/100 (quality, fit, speed and memory use) sets the ranking. | MiMo V2.6 Distill Qwen 9B | Q4_K_M | 7.9 GB | 39.1 tok/s | Runs great |
| 73Great quality (A) · 73 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 84/100 (quality, fit, speed and memory use) sets the ranking. | Ornith 1.5 9B | Q4_K_M | 8.0 GB | 38.2 tok/s | Runs great |
| 66Good quality (B) · 66 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 83/100 (quality, fit, speed and memory use) sets the ranking. | ERNIE 4.5 21B-A3B Thinking | Q4_K_M | 15.7 GB | 86.9 tok/s | Runs welltight fit |
| 66Good quality (B) · 66 of 100: how capable the model is at Q4_K_M, whatever it runs on. Match score 83/100 (quality, fit, speed and memory use) sets the ranking. | Maple Preview (20B-A1B) | Q4_K_M | 14.3 GB | 135 tok/s | Runs welltight fit |


Best Image models for the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 89Excellent quality (A+) · 89 of 100: how capable the model is at FP8, whatever it runs on. Match score 93/100 (quality, fit, speed and memory use) sets the ranking. | FLUX 3 Image Klein | FP8 | 12.4 GB | 13 s | Runs great |
| 83Great quality (A) · 83 of 100: how capable the model is at Q8 GGUF, whatever it runs on. Match score 92/100 (quality, fit, speed and memory use) sets the ranking. | Z-Image Turbo | Q8 GGUF | 13.0 GB | 7.3 s | Runs great |
| 84Great quality (A) · 84 of 100: how capable the model is at Q8 GGUF, whatever it runs on. Match score 90/100 (quality, fit, speed and memory use) sets the ranking. | ERNIE-Image Turbo | Q8 GGUF | 15.0 GB | 9.3 s | Runs welltight fit |
| 77Great quality (A) · 77 of 100: how capable the model is at Q8 GGUF, whatever it runs on. Match score 89/100 (quality, fit, speed and memory use) sets the ranking. | FLUX.2 [klein] 4B | Q8 GGUF | 10.5 GB | 2.9 s | Runs great |
| 83Great quality (A) · 83 of 100: how capable the model is at Q8 GGUF, whatever it runs on. Match score 87/100 (quality, fit, speed and memory use) sets the ranking. | FLUX.2 [klein] 9B | Q8 GGUF | 12.3 GB | 5.5 s | Runs greatencoder unloaded after use |
| 80Great quality (A) · 80 of 100: how capable the model is at FP8, whatever it runs on. Match score 83/100 (quality, fit, speed and memory use) sets the ranking. | Z-Image | FP8 | 12.6 GB | 39 s | Runs well |

Best Video models for the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 49Fair quality (C) · 49 of 100: how capable the model is at FP8, whatever it runs on. Match score 77/100 (quality, fit, speed and memory use) sets the ranking. | LTX-Video 2B | FP8 | 10.8 GB | 57 s | Runs great |
| 44Fair quality (C) · 44 of 100: how capable the model is at FP8, whatever it runs on. Match score 74/100 (quality, fit, speed and memory use) sets the ranking. | CogVideoX 2B | FP8 | 11.0 GB | 2.3 min | Runs great |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | Wan 2.1 T2V 1.3B | FP8 | 12.8 GB | 9.1 min | Runs well |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | CogVideoX 5B | FP8 | 14.3 GB | 6.8 min | Runs welltight fit |
| 53Fair quality (C) · 53 of 100: how capable the model is at FP8, whatever it runs on. Match score 72/100 (quality, fit, speed and memory use) sets the ranking. | CogVideoX 5B I2V | FP8 | 14.9 GB | 6.8 min | Runs welltight fit |


Best Decision models for the NVIDIA RTX Spark N1X (5120-core GPU) (32 GB)
| Quality | Model | Quant | Memory | Speed | Runs |
|---|---|---|---|---|---|
| 86Excellent quality (A+) · 86 of 100: how capable the model is at F16, whatever it runs on. Match score 93/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3.5 | F16 | 3.3 GB | 29 ms | Runs great |
| 90Excellent quality (A+) · 90 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 92/100 (quality, fit, speed and memory use) sets the ranking. | Qwen3 Reranker 4B | Q8_0 | 6.4 GB | 145 ms | Runs well |
| 84Great quality (A) · 84 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 92/100 (quality, fit, speed and memory use) sets the ranking. | Intern-Decision 4B | Q8_0 | 6.8 GB | 95 ms | Runs great |
| 84Great quality (A) · 84 of 100: how capable the model is at F16, whatever it runs on. Match score 92/100 (quality, fit, speed and memory use) sets the ranking. | Jina Reranker v3 | F16 | 3.3 GB | 29 ms | Runs great |
| 88Excellent quality (A+) · 88 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 92/100 (quality, fit, speed and memory use) sets the ranking. | zerank-2 | Q8_0 | 6.4 GB | 145 ms | Runs well |
| 82Great quality (A) · 82 of 100: how capable the model is at F16, whatever it runs on. Match score 91/100 (quality, fit, speed and memory use) sets the ranking. | d1 3B | F16 | 8.2 GB | 86 ms | Runs great |
| 82Great quality (A) · 82 of 100: how capable the model is at F16, whatever it runs on. Match score 91/100 (quality, fit, speed and memory use) sets the ranking. | mxbai-rerank-large v2 | F16 | 5.0 GB | 67 ms | Runs great |
| 86Excellent quality (A+) · 86 of 100: how capable the model is at Q8_0, whatever it runs on. Match score 91/100 (quality, fit, speed and memory use) sets the ranking. | Shieldstral 1.0 3B | Q8_0 | 6.2 GB | 139 ms | Runs well |


Estimates come from published hardware specs and our open formulas, not from running the model on your machine. Real speed varies with runtime, drivers and settings. Numbers marked “Measured” come from a linked benchmark.